

Enterprises settled the question:“is my software actually working” about a decade ago. Not by hiring more people to read logs, but by instrumenting the data plane once and letting anyone query it. Observability became infrastructure, and the people who used to read logs went and solved harder problems.
GRC has never had that moment. We still read the logs, opine, and complete the attestation.
The strange part is that demoing continuous control monitoring is no longer hard. You can integrate the stack, map controls to a framework, and switch on live testing in about thirty days — TrustCloud’s Chief Product Officer, Tejas details exactly how. Every enterprise I talk to either has a demo from a leading vendor or an internal pilot running.
And then it stops. The demo proved the concept and became the ceiling.
That gap, between a program that works and a program that covers anything, is where a decade of GRC transformation went to die. It’s worth being precise about why.
Why programs stall past the demo
The transformation you were sold never landed. The systems-integrator model priced services at 2–3× the ACV of the platform, ran on a three-year timeline, and delivered into an environment that had already moved. By go-live, the application estate had reorganized, the framework had been revised, and the control set had grown. That isn’t a failure of execution; it’s a failure of arithmetic. And the multiple is the argument: 2–3× ACV in services isn’t an implementation cost, it’s the cost of humans translating controls one at a time, and it recurs every time the estate changes.
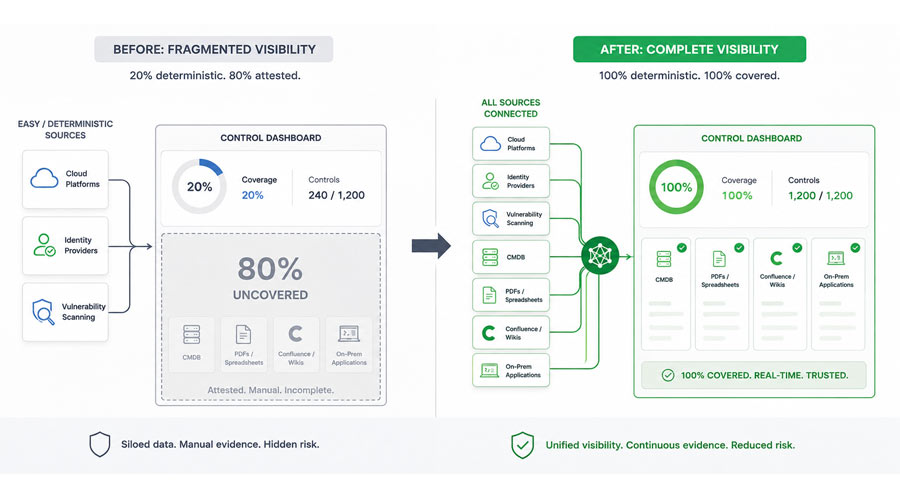
Enterprise GRC is still attestation-dependent underneath. Automating the convenient 20% cloud configuration, identity, vulnerability scanning takes three integrations. The remaining 80% is custom applications, unstructured data, and humans reviewing screenshots and logs. The approach has survived ten years because the CISO seeing the dashboard at the end doesn’t know where it came from, resulting in a program that is 20% deterministic and 80% attested.
Fundamentally, such a GRC program is an attested program with better dashboards, not a data-driven continuous system.
Most of the control landscape lives in unstructured data. CMDB records, policy PDFs, DPAs, prior assessment history, change tickets, architecture docs, Confluence pages is the lion’s share of attestation data today. Technical cloud controls were never the hard part as they emit machine-readable state by default. Documentation and process controls are the majority of any enterprise control set, and they are where coverage stalls, because there is nothing to query. Add the on-prem and bespoke applications with no public API, and a material share of the estate falls outside every vendor’s integration menu.
Machines and humans process data differently, and GRC was written for humans. A control statement is a sentence. A test is a query. Every control needs someone fluent in both to sit down and translate: read the intent, define the population, decide what evidence would satisfy an auditor, then write the logic. That person is rare, expensive, and the bottleneck. Adding integrations doesn’t help them. The hundredth data feed makes the next control cheaper to source and no cheaper to translate.
Four forces, one root cause: the cost per control never falls. Coverage stops growing at exactly the point where the humans who translate controls run out of hours: somewhere around two dozen controls for most pilots.
Programs that scale don’t add tests faster. They change what a test costs to create. One-off automation scales linearly with headcount: each control consumes a human translation, and the next one costs what the last one did. Change the layer underneath and coverage scales with the number of data feeds instead — a far smaller number, and one that stops growing once the systems of record are connected.
The Fabric: bring any data, really
Everyone integrates with AWS. Every leading vendor ships 150–300 connectors. That part is table stakes.
The claim that gets overlooked is the other half of the estate, where the cost of connecting anything without a default connector is astronomical. Our answer: an AI-readable SDK that handles structured and unstructured data, so the on-prem application, the internal tool, and the bespoke platform inherited three acquisitions ago all feed the Hybrid Data Fabric at scale.
Document repositories and policy corpora are ingested as first-class, addressable sources — not stapled on as artifacts sitting next to a control. Policy PDFs, CMDB records, DPAs, and change tickets stop being attachments someone hunts down at audit time. They become data you can test.
The CMDB deserves its own sentence, because it is the most underused asset in the enterprise. It already knows what the estate is: every business application, its criticality, its data classification, its owner. Most GRC programs treat it as a reference document someone consults during scoping season. We treat it as the population definition.
The Reasoning: a semantic layer and a translator
This is where the cost per control collapses.
The ControlGraph is the semantic layer and relationship model. Controls map to policies, risks, applications, infrastructure, security tooling, frameworks, and business commitments. Scoping is dynamic: business rules are expressed over system definitions and re-evaluated whenever a system is added or changed. Onboard an application on Monday and it inherits its control requirements on Monday.
TestAI does the translation that used to require a human to be fluent in two languages. A control statement written in plain English becomes an executable test configuration against the normalized data feeds. Evidence is produced as a byproduct of execution rather than collected as a separate exercise.
Concretely:
“Critical applications storing PHI are authenticated using MFA.”
The scoping filter selects the matching population of systems. A joined query pulls identity-provider connection state against the application inventory. Pass/fail criteria evaluate MFA configuration. The evidence is the exact fields and records the test read, plus the test-run and data-refresh metadata.
No one wrote a query. No one collected a screenshot. No one had to convene a GRC analyst and a data engineer to agree on what “critical” means, because that definition lives in the scoping filter and is applied identically every run.
That is the mechanism that breaks the cost-per-control curve. Two figures make it concrete:
- Control mapping and evidence work runs at roughly an 80% AI / 20% human split: the ratio that makes an enterprise rollout credible against a several-hundred-control target.
- Seven days from an available data feed to an automated control. Contractually committed, not aspirational.
The Signal: the CISO owns the risk, the CTO owns the code
Skip the dashboard rollout and save yourself 6 months. Signal lands in ServiceNow IRM and SecOps, Splunk, Jira, BI tooling, or embedded widgets, wherever the team already works. Instead, the last mile of continuous control monitoring becomes a closed remediation loop.
The structural problem in one sentence: a control failure surfaces in a GRC tool, but the authority to fix it lives in Jira, on an engineering team that never sees the finding.
So alongside ServiceNow IRM as the GRC repository, TrustCloud is live on the Atlassian Marketplace, inside Jira — the platform where the world’s software actually gets built, and where the engineers who own the fix already spend their day. Findings become Jira tickets routed to the real technical owner with GRC-validated evidence attached. Evidence uploaded on a Jira issue is ingested into the graph and analyzed by AI that validates whether it satisfied the control, what’s missing, and what’s next.
This results in a control failure to remediated finding within 24 hours, a mean time to risk remediation from six months to 18 hours, with closed-loop accuracy and traceability validated above 90%.
Six months to 18 hours. That’s not a faster process. That’s a fundamentally different system.
What this unlocks
So why should these matter? Ultimately, in the age of AI, the three metrics a CISO is getting asked about regularly:
- Mean time to detection. Control failure to finding in under 24 hours. A Fortune 100 technology company saw first findings inside 24 hours and reached 20 controls across 12 data feeds by day 45, with an industry-benchmarked residual-risk view the CISO could defend.
- Mean time to remediation. A global technology conglomerate moved application assessments from three to four weeks per app to under 90 minutes with fixes to findings taking place within 48 hours of discovery.
- Mean time to coverage. A Fortune 100 pharmaceutical took crown-jewel application monitoring from roughly 20% under manual questionnaires to 96% under a continuous monitoring program. A comparable pharma went from 5% sampling to 100% landscape-based testing while another team went from 20 manual application assessments a year to 200–300 assessed weekly — same team, same budget.
The number you’ll soon be asked for
The CISO who can state control coverage as a percentage of the estate is running a categorically different program from the one reporting on a sample. Not a better-instrumented version of the same program.
Boards have started asking for the percentage. Audit committees will ask next. The answer is either a number about your estate or a number about your sample, and everyone in the room can tell which one they’re hearing
See what it takes to scale continuous control monitoring beyond the demo.
